When Code Becomes Cheap, Review Becomes Expensive
How I handle code review when AI coding agents generate changes faster than humans can review them, using planning, guardrails, independent reviews, and selective CI checks.
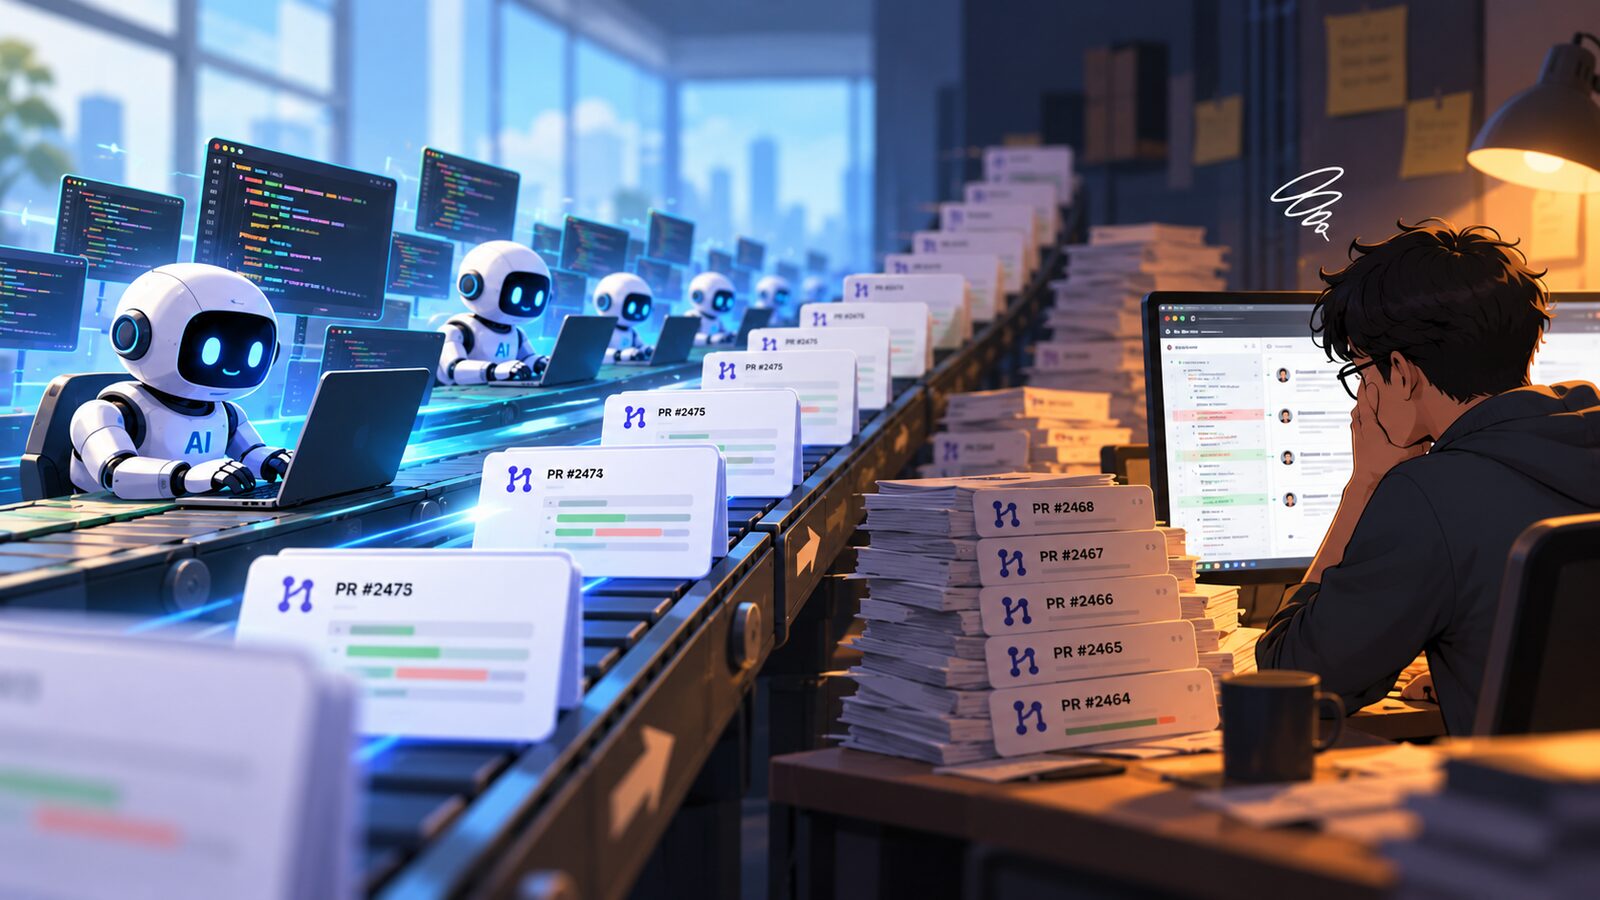
AI coding agents have changed how quickly we can ship code. What used to take hours can now take minutes. With multiple agents working in parallel, it's entirely possible to produce several commits or PRs before a human reviewer finishes looking at the first one.
But there's a problem: our ability to generate code is growing much faster than our ability to review it.
Anthropic has reported a 200% increase in code output per engineer over a year, with code review becoming a bottleneck.
So, what do we do? Ask developers to read faster? Add more reviewers? Let AI approve AI-generated code?
I've been experimenting with a different approach: reduce the amount of review needed, rather than just accelerating the review itself.
Here's the workflow I've settled into.
1. Spend More Time Planning, Not Less
This might sound counterintuitive. If AI can implement something in minutes, why spend so much time preparing the task?
Because the faster implementation becomes, the more expensive a wrong decision becomes.
I use Linear to define the task before letting Claude Code touch the codebase. Three things matter most:
- What needs to be accomplished: Clear requirements and expected behavior.
- What success looks like: Specific, verifiable acceptance criteria.
- What should NOT be done: Constraints, boundaries, and approaches I want to avoid.
That last point is particularly important. Coding agents are very good at finding ways to accomplish a goal, but they can also introduce unnecessary abstractions, expand scope, or solve problems you never asked them to solve.
I don't outsource this planning responsibility to AI. I might use AI to challenge or refine my thinking, but the decisions are mine.
Once the task is clearly defined, I give the Linear ticket to Claude Code and let it implement or fix the issue.
The principle is simple: Spend human intelligence on deciding what to build, not supervising every line of how it gets built.
2. Prevent Mistakes Before They Happen
Code review shouldn't be the first time we discover that an agent violated our engineering standards.
I maintain repository-level instructions covering coding conventions, architectural constraints, and known anti-patterns.
These instructions help the agent understand not only how we write code, but also the approaches we deliberately avoid.
I also configure Claude Code hooks to run the necessary tests when the agent finishes its task.
Instead of relying on the agent to remember to test, the workflow triggers those checks automatically.
This gives us two layers of prevention:
- Instructions reduce the chance of generating undesirable code.
- Hooks and tests catch problems before the changes reach a PR.
Neither is perfect. Instructions can be misunderstood, and tests only catch what they cover. But every problem caught here is one less problem waiting for a human reviewer.
3. Give the Code a Fresh Pair of Eyes
One problem I kept encountering was how to review code Claude Code had just written.
Asking the same agent to review its own implementation isn't ideal. It still has the original decisions and reasoning in context, so it may be inclined to defend those decisions rather than challenge them.
Starting a completely separate session helps with that, but introduces another problem: the new session doesn't know why particular decisions were made.
And if you ask that new session to fix something, it may unintentionally violate the original requirements.
To address this, I built an open-source Claude Code plugin called Fresh Eyes.
The idea is straightforward:
- The main coding agent completes the implementation.
- Fresh Eyes launches a read-only review subagent with its own clean context.
- The reviewer examines the changes independently, using the requirements and constraints without inheriting the implementation reasoning.
- The findings are returned to the original coding session.
- The main agent, which still understands the implementation context, evaluates and fixes the findings.
This separates two responsibilities that are often mixed together:
Independent judgment for finding problems. Contextual understanding for fixing them.
I can trigger the plugin manually using:
/fresh-eyes:review
Or I can add it to the agent instructions so it runs after each implementation task.
It's not a guarantee that every finding will be correct. But it's a practical way to introduce independent scrutiny without losing the context needed to make appropriate fixes.
4. Use AI Review in CI, but Be Selective About When It Runs
The next layer is PR review.
I use a custom Claude review agent built on the Claude GitHub application, rather than Anthropic's official Claude Code Review service.
I compared their performance for my use cases and found that my custom implementation provides comparable practical value at significantly lower cost.
Unlike Fresh Eyes, which focuses on reviewing the implementation against the original task, the CI review takes a broader, project-level perspective.
It focuses particularly on:
- Security: Identifying insecure coding patterns, authentication or authorization issues, and potential exposure of sensitive information.
- Vulnerabilities: Looking for exploitable weaknesses, unsafe dependencies, and other security risks introduced by the changes.
- Project-wide impact: Examining how the changes affect existing functionality, shared components, APIs, and other parts of the codebase, including potential regressions or unintended side effects.
This separation is intentional. Fresh Eyes challenges implementation decisions, while the CI reviewer looks beyond the immediate task to identify risks affecting the wider system.
Another advantage of a custom GitHub Action is control over when reviews run.
Reviews can be triggered on every push, through specific tags, or by comments on a PR.
I mostly use specific tags and manual comment triggers.
Why not trigger reviews automatically on every push?
Because coding agents can produce a lot of intermediate commits. Running a full AI review on each push can waste tokens and generate feedback on code that's about to change again.
I prefer to request a CI review when the implementation is reasonably stable.
More automation isn't always better automation.
Sometimes a deliberately placed manual trigger is more efficient than an always-on process.
5. Human Review Becomes the Final Judgment, Not the First Line of Defense
By the time a PR reaches me, it has ideally passed several checks:
- The task was defined with clear success criteria and boundaries.
- The coding agent followed repository conventions.
- Required tests have run.
- Fresh Eyes has independently examined the implementation.
- A separate CI review agent has checked for security risks, vulnerabilities, and project-wide impact.
At that point, I focus on the review reports, the significant decisions, and a quick examination of the code.
I don't try to manually reconstruct every implementation detail.
For ordinary, low-risk changes, this can substantially reduce review effort.
For security-sensitive changes, major architectural decisions, data migrations, or other high-impact work, I still believe deeper human review is necessary.
The goal isn't to eliminate human responsibility. It's to spend human attention where it matters most.
6. AI Review Isn't a Replacement for Engineering Judgment
There's a tempting assumption that if one AI writes the code and another AI reviews it, the result must be reliable.
I don't think that's a safe assumption.
Two agents can share blind spots. A review agent can miss a business requirement. Tests can pass while the behavior is still wrong.
And an AI reviewer can produce convincing explanations for findings that aren't actually problems.
That's why I treat AI reviews as supporting evidence, not unquestionable approval.
This also brings us back to planning.
An agent might verify that an implementation is internally consistent. But it doesn't necessarily know whether we should have implemented it that way in the first place.
That decision still needs engineering judgment.
7. The Real Shift Is Where We Spend Human Attention
The traditional workflow looks roughly like this:
Human writes code → Automated tests → Human reviews code → Merge
My current workflow looks more like:
Human defines intent → AI implements → Automated checks → Independent AI review → CI AI review → Human validates → Merge
This isn't about replacing developers with coding agents.
It's about changing the developer's role from manually producing and inspecting every line of code to defining intent, establishing constraints, evaluating evidence, and owning the outcome.
As coding agents become faster, I expect the value of clear requirements, good architecture, reliable verification, and engineering judgment to increase.
The important question is no longer just:
How fast can we write code?
It's:
How can we trust the code we're producing without making human attention the limiting factor?
I don't have a perfect answer yet. But moving review earlier, preventing predictable mistakes, using independent agents, and keeping humans focused on consequential decisions has been a practical approach for me.
And I suspect the next generation of engineering workflows will spend much more effort on designing systems of verification, not simply generating more code.